About Me

My photo
Rohit is an investor, startup advisor and an Application Modernization Scale Specialist working at Google.

Friday, October 13, 2017

Pushing WebSphere Application Sever Applications to Cloud Foundry with Open Liberty

Thanks to a  friendly nudge and significant contributions from Michael Wright, I have had the opportunity to reacquaint myself with an old friend - the WebSphere Liberty Profile Buildpack. In case you missed it, in a bold move IBM open sourced the WebSphere Liberty Profile their lightweight application server.  Open Liberty as it is called now is an excellent landing spot for ALL current WebSphere Application Server classic apps. 

To get them running with the least amount of changes WebSphere apps should typically be pushed with the WebSphere Liberty Profile Buildpack. The Liberty buildpack has myriad ways of configuring it with lots of environment variables to control the set of features and WebSphere server configuration and so on ... Here are some best practices to follow a repeatable and simple process of migrating your apps using Open Liberty to Cloud Foundry: 

1. It’s OK to develop on STS or Eclipse, but don’t rely on Eclipse to package the application inside the server configuration.

2. Develop your application with Open Liberty's maven plugin. If you have an existing project convert it to Open Liberty by cloning and copying the build pom.xml from one of the guides.  This is a very similar to a spring boot like experience for JavaEE/EE4J.  An alternate way of developing is to configure the server.xml for your server and then keep copying the app to the dropins folder. 

3. After your application runs locally package a Liberty server with your application in the dropins folder and the right server configuration in the usr directory. This is akin to packaging a fat jar for your WebSphere app. Creating a server package avoids the headache of configuring the buildpack with the right set of environment variables when pushing the app. 
server package defaultServer --include=usr 

4. When the application does run in Cloud Foundry play special attention to this message 2017-10-12T22:59:27.80-0400 [APP/PROC/WEB/0] OUT [AUDIT] CWWKT0016I: Web application available (default_host): http://9e1d0c1c-a318-46eb-7760-0302:8080/war-with-resource/
This informational message reveals your context-root for your application. Context root determination for an app is a multi-step evaluation based multiple files.

The context-root attribute specifies the entry point of the deployed application. The entry point of a deployed application is determined in the following precedence:
- context-root in the server.xml file
- application.xml, if an EAR application
- ibm-web-ext.xml, if a web application
- name of the application in the server.xml file, if a web application
- Directory name or the file name relative to the drop-ins directory of Liberty
My rule of the thumb is NEVER to set a context root and manage the public URL via a Cloud  Foundry route. By default the buildpack set context root for an ear file is "/".

Notes of Caution 
  1. Your application does not need to be cloud native to run on Cloud Foundry. You can push zero factor apps to CF no problem. If the application does not function correctly look under the hood by cf ssh'ing into the container and examine the final server.xml. If your EE resources are not being served or recognized by the container check your list of features and corresponding configuration in server.xml
  2. WebSphere Liberty Profile Buildpack provisions the DEV licensed WebSphere Liberty Profile runtime and NOT the Open Liberty runtime. To avoid licensing headaches you should fork the Liberty Profile Buildpack to provision the Open Liberty runtime instead of the DEV only licensed WebSphere Liberty Profile runtime.

In Closing

If you want to completely avoid the IBM apple cart, an excellent alternative is the TomEE buildpack which also runs JavaEE7 Full , Web and micro-profiles  ear, war,  fat and skinny jar apps. For more on this topic read a previous post yes-we-can.

Replatforming  is just the first phase of your multi-step journey to Cloud Native.  Your ideal end-state is to make the app cloud native and therefore vendor and platform agnostic leveraging the app  dialtone based on the contracts established by the  platform API. 

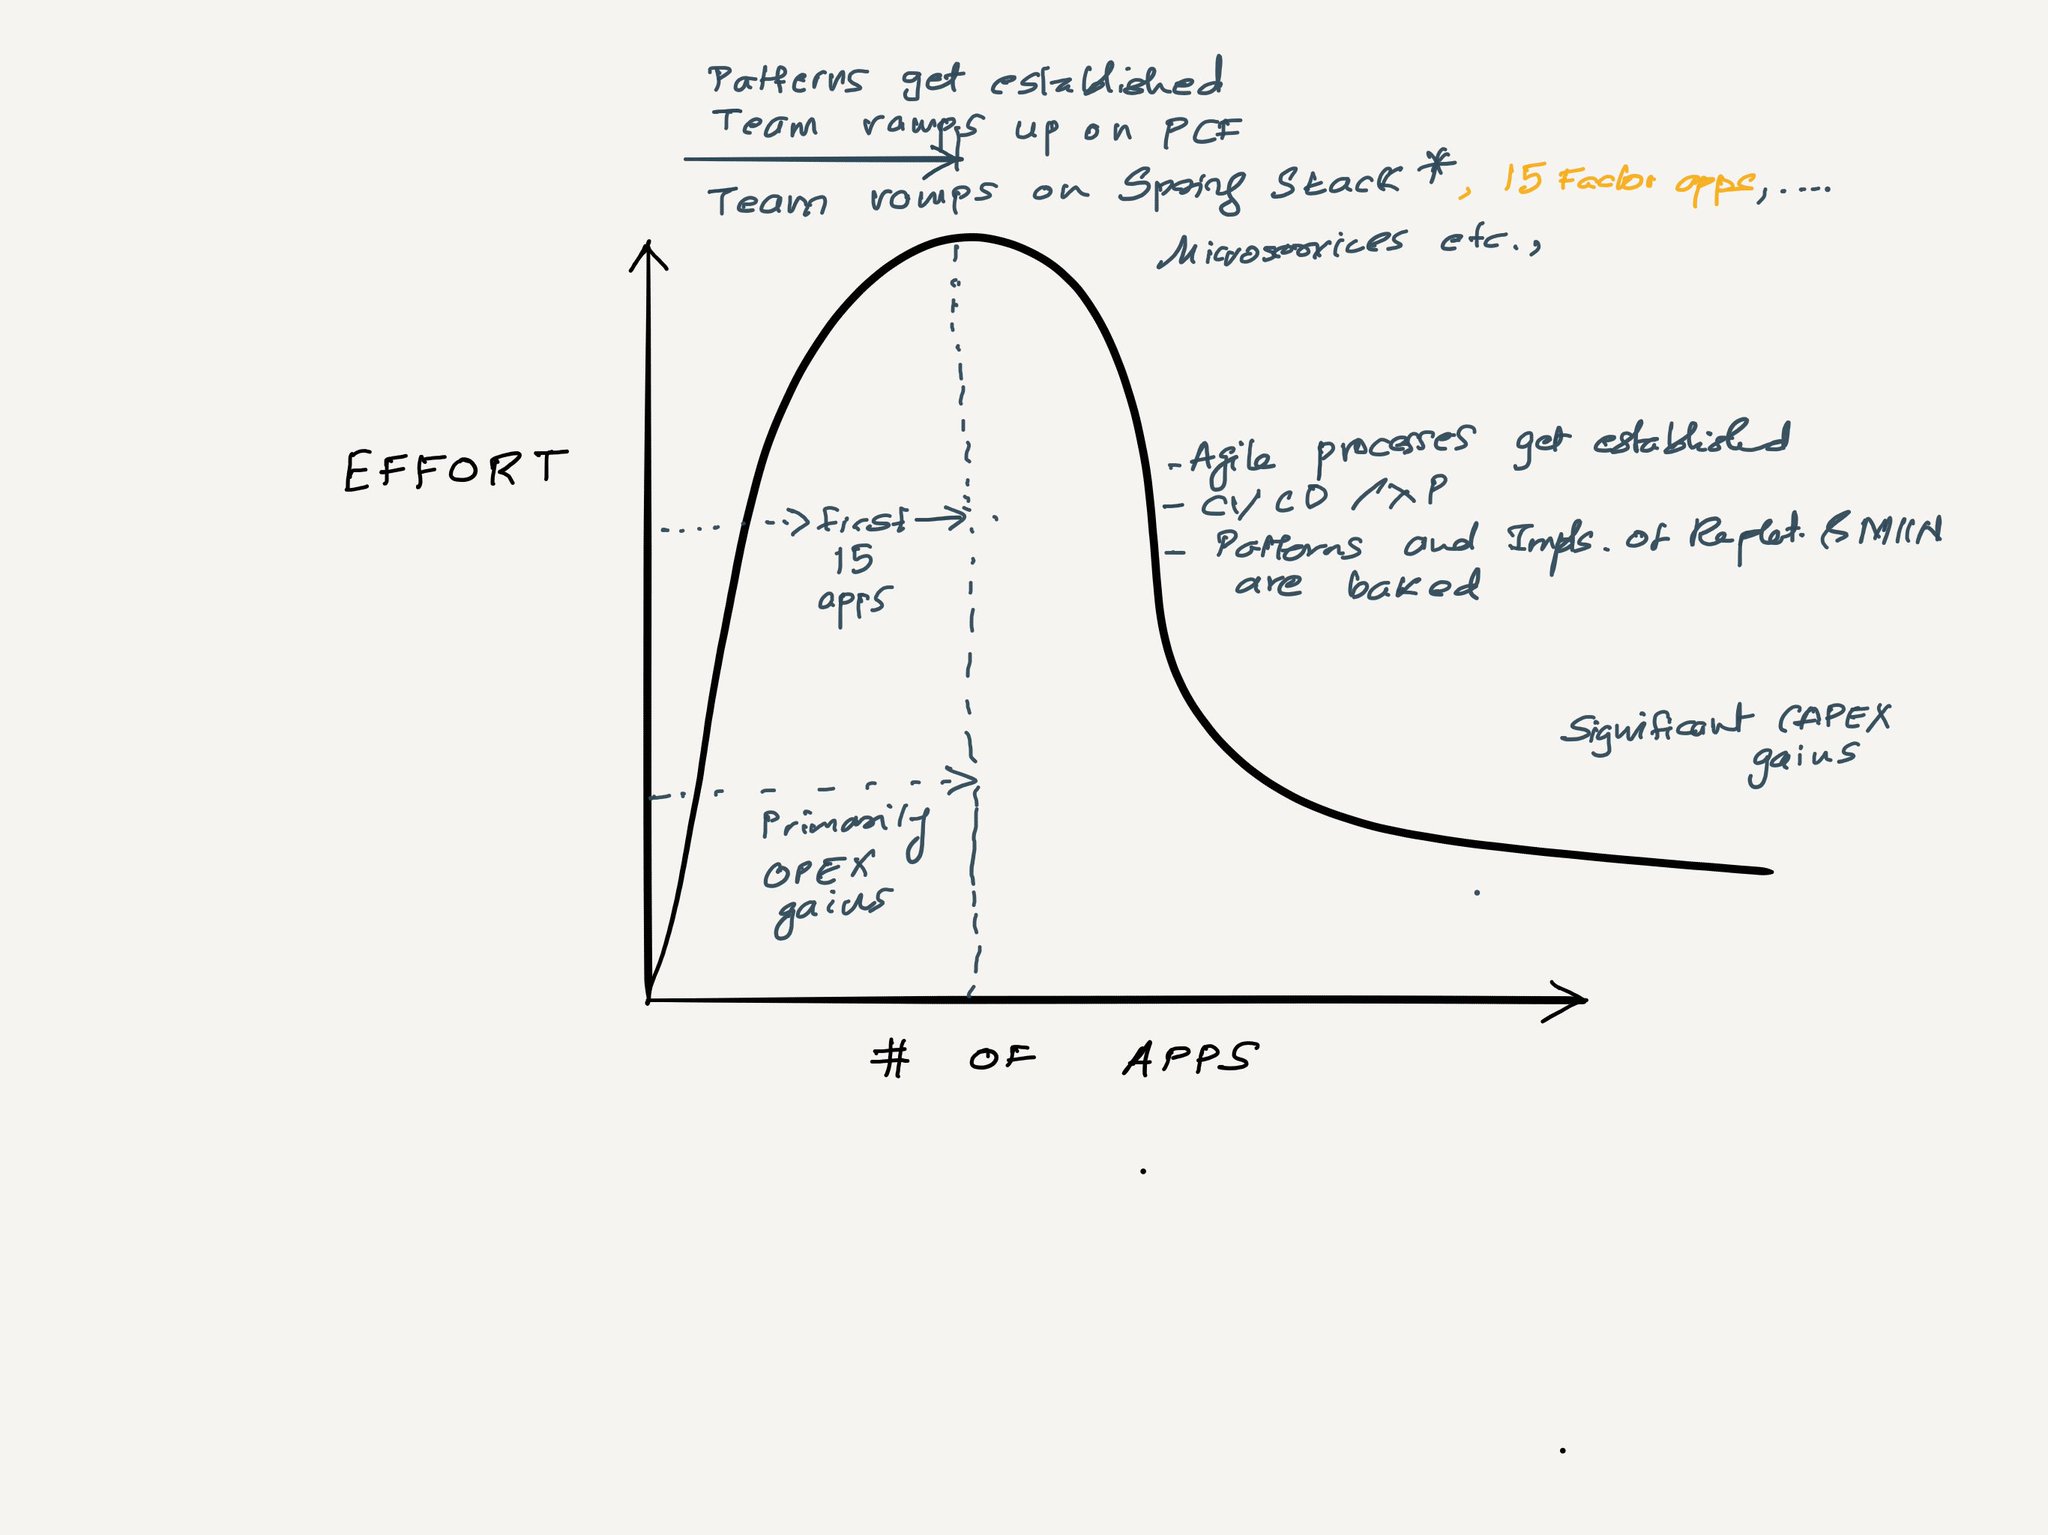
The Cost Curve of Application Replatforming


Tuesday, October 10, 2017

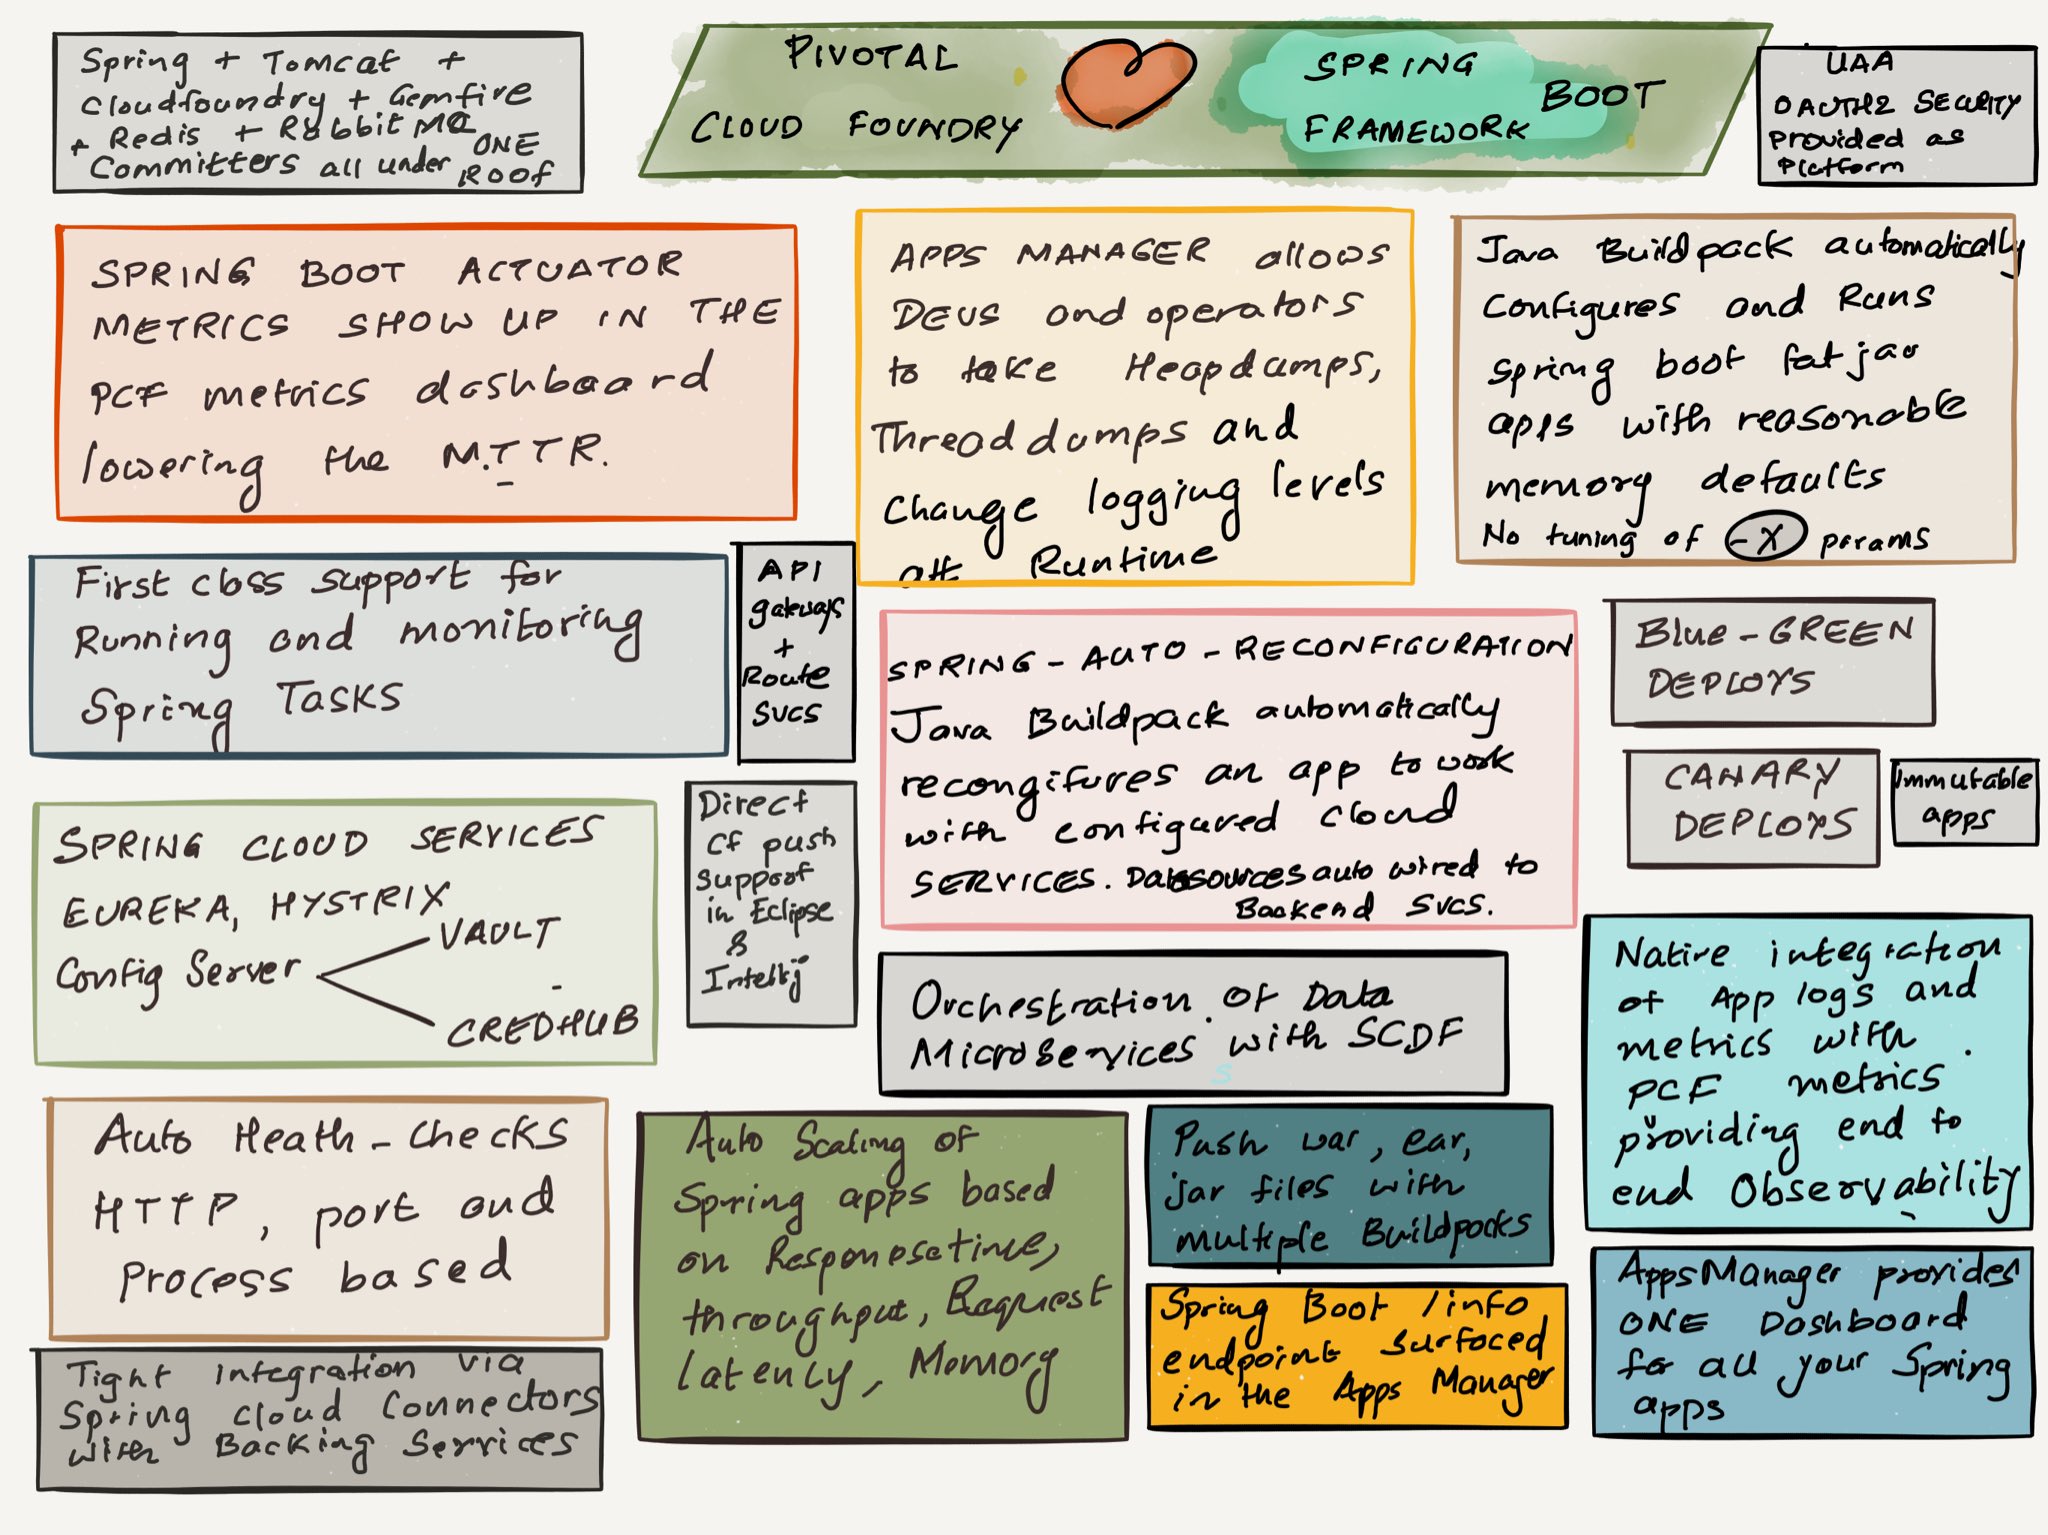
PCF Is the best place to run Spring Apps


Forgot to mention the auto patching of vulnerabilities by the buildpack. Instead of the developer managing all the middle layers the CF buildpack  curates and maintains this list. 

Sunday, October 8, 2017

Emergent Systems and the need for Chaos Architecture

The ideas below are an amalgamation of key signals from Adrian Cockcroft, Neal Ford, Matt Stine, Russ Miles, Michael Nygard and the rockstar engineers of Netflix who have pioneered Chaos Engineering.

For the long term survival of your microservices system some key concepts have now come together chiefly: anti-fragility, continuos partial failure  and evolutionary architecture. 

Since all of us seem to building networks of distributed microservices there is no way to test the emergent behavior of these systems in test. We HAVE to run controlled experiments in production. Chaos engineering and a chaos friendly architecture is critical for enterprises to maintain availability of their applications and survive breaches.  Adrian Cockcroft in his recent Cloud Native London keynote espoused four layers, two teams and an attitude.

Chaos Engineering is the discipline of experimenting on a distributed system
in order to build confidence in the system’s capability
to withstand turbulent conditions in production.


Chaos engineering is the best continuously holistic function to evaluate a distributed system to withstand impact and external perturbation. So what are the different levels at which chaos engineering

Layer-1: Infrastructure: Lay out the infra. so that there is no SPOF. Multiple zones, regions. app is distributed enough times and enough ways - diversity in the infrastructure

Layer-2: Switching and interconnect. Strategy for interconnecting. NO SPOF => data in more than one place. This will require data to be replicated in a different side of the world. Data needs be more than one disk - in  a different building. Routing needs to transparently handle failover across datacenters. Unfortunately DR routing/failover is the Least well tested set of components in the system. Usually all error handling code explodes at impact. Once the fallen datacenter comes up there is a need to Re-route and re-synchronize - introduce anti-entropy people back into the system. It is critical to regularly test Failover regularly to the backup datacenter. Test HA/DR across data-centers  properly instead of availability theater.

Layer-3: Application Layer: What does app do when it  experiences data loss , n/w connectivity failures, timeouts, error returns, slow responses, network partitions - app hangup - goes 100% busy
Single functions and microservices can be tested to one thing. Lambda is easy to develop for. Unit of testing and deployment. Monoliths lead to combination testing. Lot of variations

Layer 4 People: When machines  mis-behave people really screw it up. Usually folks made it worse. There are countless stories of systems that were thrashed by the operators due to a comedy of errors. It is super-important to practice gamedays similar to how children in kindergarten practice a fire drill.  Chernobyl.  Reboot may be the wrong thing to do when you have services. Play out fire-drills so that when there is an actual fire people take the right action - disaster preparedness.  Practice, Practice, Practice. ... Fire drills

Tools that attack the different layers.
  1. Game Days - exercise outage. Right way everyone is to behave. folks on a call. how to find the dashboards etc. as well digging into details
  2. Simian army- Tests once a month
  3. FIT - Deep injection of failures. CHAP. Chaos automation platform
  4. Gremlin Inc. -  Auto mates chaos engineering scenarios and gamedays.  Undo button. Safer with automation.
  5. There is an excellent catalog tools at the end of the chaos engineering eBook
Two Teams
  1. Security Blue Team/Security Red Team(Break into your site)
  2. Chaos Engineering Team/SRE Team

Companies offer services to make System secure and resilient.
  • AttackIQ
  • Safebreach
  • Spear fishing

Attitude - Improve your chaos posture
- OReilly book - Chap and the Chaos Maturity Model gives a roadmap to improve your chaos game.
- Chaos engineering community day coming up - London this is becoming a thing

If you want to create a system with 99999/99999999 availability it is important to establish  a Chaos Engineering Practice that keeps the team safe, and whole stack reliable.

Attitude

Go run a gameday. People experienced in simulating outages. easy cleanup.
Start at top and work your way down.


Tuesday, October 3, 2017

Pushing Zero Factor Apps to Cloud Foundry

Often times I hear the refrain that Pivotal Cloud Foundry is only suitable for cloud native apps that adhere to the 12 or 15 factors. This is like saying that the Spring is XML centric in 2017 or that Java EE is heavyweight in 2017. Cloud Foundry is a big tent platform that is suitable for running all kinds of workloads across languages and runtimes. 

In this post, lets disprove the myth by looking into what it will take to push a 0 factor app or a cloud-ANGRY app to Pivotal Cloud Foundry.  On a slight tangent the definition of cloud native keeps expanding. First we had the 12 factors from Heroku. Thereafter we added authentication/authorization, monitoring and API First making it 15. Recently Adrian Cockroft  espoused the following Cloud Native Principles 1. Pay As You go 2. Self Service- no waiting 3. Globally distributed by default 4. Cross-zone/region availability models 5. High Utilization- turn idle resources off and 6. Immutable Code Deployments.

So here it goes ....

1. One Codebase, one application
Violation of this rule leads to multiple application emerging from a single codebase or a mono-repo. Why is this pattern so bad - Because it leads to anti-patterns where updating one dependency leads to a cascade affecting all other apps built from the same repo. This  is akin to the domino effect. If you can sustain the pain of building all your apps from one repo - leading to a cascade of inter-dependent updates you don't need multiple repos. You can violate Conway's law - if you have a  complete holocracy. In fact google stores billions of Lines Of Code in a single monorepo.  Cloud foundry does NOT care if your app was built from one repo or sourced from multiple repos. 

2. API First
So this principle states that Built into every decision you make and every line of code you write is the notion that every functional requirement of your application will be met through the consumption of an API. You could of course  write code without interfaces or APIs or achieving market fit. At the extreme end you would ONLY build the API if you needed it and when there were multiple consumers and customers necessitating it. If you have only one consumer then why have a consumer driven contract. Talk the other team and establish a partner relationship. Again Cloud Foundry does NOT care if you are API first or API last. As app owners you have to live with the implications of this decision not the platform. 


3. Dependency Management
Software engineering practice dictates that we should explicitly declare and isolate dependencies. Most modern apps put an onus on independences i.e. package all the downstream dependencies including the application server in a fat jar. You don't rely on the implicit existence of system wide packages or mommy servers  like WebSphere. On the flip side you can definitely let the application server bring majority of the dependencies or use a method of layering with multi-buildpacks to inject your dependencies. Cloud Foundry has multiple options for pushing apps including ear, war, jar and docker files. Buildpacks like the Liberty Profile, JBOSS or TomEE will gladly allow you to keep your app lean and source all the dependencies from the application server classpath. So instead of a fat jar you can have the buildpacks create the Mommy server.

4. Design, Build, Release and Run
Strictly separate the build and run stages. Build one artifact and configure it at runtime for the environment. Release = (Build + Environment specific settings + app-specific configuration).  This principle allows for auditability and rollback. In the absence of separation in the build and run stages you are implicitly acknowledging that rollback is never an option and you don't need to track your past releases. Code and features are always moving forward in production. Everyone lives and codes on the master branch. You could completely violate this rule by packaging separate artifacts for every environment. As long as you have an ITIL process to validate such a process and the appropriate org structure it is possible to build apps-per env and throw them over the wall. Again this way severely defeats the purpose of devops and makes life of service reliability engineers ridiculously difficult. As long as you are using the environment variables from the right org and space you could pull this off with zero changes to the app in Cloud Foundry.

5. Configuration, Credentials and Code
Ideally you should keep this holy trinity separate from each other and bring them together ONLY at runtime in the platform; however I contend in 80% of the cases these three stay together and can be pushed together to Cloud Foundry. Of course the app is less secure and brittle since configuration is hardwired and credentials hardcoded, the app can still function correctly on Cloud Foundry. There is no explicit requirement that code should be separated from credentials and configuration should be externalized. As long as the properties are correct and location independent, the app will work with configuration bundled within the app 

6. Processes: Any state that is long lasting outside the scope of the request must be externalized. This allows for processes to be treated like cattle and not pets. This constraint can be violated by keeping long running state like caches, sessions and other user data across requests. As long as you can live with the risk of the occasional user seeing errant 500 responses when the server goes down this drawback can be tolerated. A side-effect of keeping state within the container is that your JVM sizes will be atypically large and rebalancing your app across diego cells will become time consuming.

7. Port Binding
The platform will perform the port management and assign the container a port through the environment instead of hardcoding the port in the server configuration. It is difficult to directly violate this principle since cloud foundry is responsible for port assignment and creation of routes to the app instance. Using container-to-container networking you may be able to overcome this constraint. 

8. Concurrency
Cloud apps should scale out using the process model. There is nothing in Cloud Foundry stopping you from scaling vertically instead of horizontally. Go crazy and push with a -Xmx of 16GB if your Diego cells  have the capacity.

9. Disposability
Ideally your app should not take more than 30s to startup or shutdown. One should always maximize robustness with fast startup and graceful shutdown. however if your app does a ton of startup initialization like priming caches or loading reference data then tune the cloud foundry cli to increase the push and the app start timeouts. If your application is BIG then you can cf push with a --no-start and then start it separately. When your app takes a significant time to startup and shutdown then it messes with the auto scaleup/scale down model of CF as well as uptime guarantees when cloud foundry redistributes your apps when new diego cells get on-boarded.

10. Dev/prod parity 
Try to keep development, staging, and production as similar as possible. This is like the advice to exercise an hour every day. Don't worry if your environments are lop-sided as long as there is some semblance of proportionality and the same PCF tech stack runs in every environment. 

11. Logs
You should treat logs as event streams unless you don't care about observability or if the logs are full of exceptions and totally useless. If the logging at INFO is so verbose so as to be of no use during debugging then don't worry about streaming the logs just call it in by persisting the logs to ephemeral disk or cheat by mounting a NFS volume and writing the logs to the volume services mounted NFS mount.

12. Admin Processes
If you don't run Run admin/management tasks as one-off processes then you will need to embed conditional logic  and APIs so as to externally trigger the admin task. You will need to map the same app under a different route to trigger a singleton instance of the management task.

13. Telemetry
Instrumenting the app for telemetry is only useful if you are going to watch the metrics and logs and take meaningful actions. In the absence of app telemetry rely on PCF metrics to provide app insight or in-built support with spring boot actuators which may be good enough for you. 

14. Authentication and Authorization
Do not rely on death star security to secure your apps. Ignore this principle at your own peril. Rely on the principle of least trust and industry standard protocols like OAUTH2 and OIDC or risk becoming the next Equifax

15. Backing Services
Treat backing services as attached resources. If you do violate this constraint then you need stateful constructs like NFS mount points via volume services and you will inject the bound service configuration in a CI pipeline. In a legacy app a lot of the backing service dependencies are already captured in a resources.xml surfaced via JNDI. Rely on buildpack auto-configuration magic to rewire these resources to cloud services automatically during cf push time.

Understand the tradeoffs and constraints and push zero factor apps to the cloud. Happy Hunting.

Wednesday, September 27, 2017

A Radar for App Transformation

My team at Pivotal is hiring Solution Architects anywhere in the USA. Please NOTE applications via greenhouse are NOT entering a blackhole. Our recruiters are looking at all CVs. We work with customers to enable digital transformation and affect change by implementing the three pillars of devops, people, process and technology. In concrete terms we help customers migrate applications and workloads to Pivotal Cloud Foundry.

To give you an idea of our tools, practices, replatforming and modernization I have created a Thoughtworks inspired technology radar for application transformation. First some definition of terms to set the context for the categories of the radar

*Replatforming* - Make minimal testable changes to an application so as to run it on PCF using an automated CI/CD pipeline. Replatforming typically entails spring bootifying an application by introducing spring boot auto starters and upgrading the dependencies of the application to work with the modern Spring ecosystem. We also typically inject data sources for downstream dependencies and fix other application concerns like logging. Like TDD we do the smallest set of changes to get the application working without affecting and external APIs or contracts. We add tests along the way as well as other production enablement features like Spring Boot actuators. There are other less tread path to replatforming as well using alternate buildpacks however; Spring Boot and Spring Cloud are in the happy path to replatforming. In a typical replatforming engagement we replatform in the order of 10-15 apps to production and leave the customer with a cookbook of reusable recipes.

*Modernization* - Make testable changes to an application (or a vertical slice of an app) to make it “run well” (achieving 15 factor compliance) on PCF. This may mean decomposing a monolith into a set of microservices aligned with their bounded contexts. Modernization is an exercise in making an application cloud native. Modernization is applied to apps of all sizes ranging from hundreds to millions of LOC. Definition of the initial scope of the work here is key to success. Pivotal practices modernization with a bunch of techniques like DDD, event storming, snap analysis, vertical slice analysis, snappy analysis, Boris Wheel and OKRs that narrow the scope of the work to intersect with the customer’s goals.We engage with the customer in XP fashion with TDD and pairing being mandatory practices. A successful app  transformation engagement unleashes a wave of such engagements across the company.

*Practices* - Our core values and fundamental techniques of XP that we do NOT compromise on. This covers a whole suite of practices like TDD, Pair-programming that we practice every day when delivering code.

*Tools* - A suite of web applications, hard and soft hacks,  the ecosystem of libraries and frameworks and the platform used to deliver app transformation.

Find the Radar here http://bit.ly/apptx-radar

 app-transformation-radar

Friday, September 22, 2017

HOW NOT TO DDD

Recently at the exploreDDD conference I gave a lightening talk on How Not To DDD.
Here are the 7 ways you should NOT do Domain Driven Design(DDD).

1. Dysfunctional DDD

Doing DDD has no effect if you do not affect organizational change that aligns with the bounded contexts.

2. Honeymoon DDD

The activities of DDD are only effective when they are done in a group to enable cross-discipline collaboration. Event storming for 7 days by two people locked in a room is a honeymoon not event storming

3. Cargo-Cult DDD

Using DDD terms but not really understanding the "Why" of practicing DDD. I usually steer clear  of folks who do this unless they are about to do real harm to the project.

4. DDD-Lite

Relying on the warm wooly blanket of tooling and IDEs to enforce all your DDD constructs. Generating package names and a proper project structure does not a DDD make. Practice DDD in the actual model and not on the surface.

5. Everybody in the Pool DDD 

When the going gets tough instead of refining the model abandon ship and start merging bounded contexts or have transactions span boundaries.

6. DDD Heaven

You have entered this state when your Process Mangers act like God objects and start orchestrating across domains and bounded contexts. 

7. Event Source/CQRS Everything DDD

Yes it is true that the ceremonies of DDD like event storming naturally lead you to messaging and event driven architectures. This does not mean that you must automatically resort to event sourcing /CQRS to implement your design. Saving state in a database and exposing APIs for event driven state transfer is perfectly fine. 


Thursday, September 21, 2017

How To Deal With XA Global Transactions in the Cloud

For decades developers have relied on global distributed XA transactions with a two phase commit protocol to coordinate  state updates across different resource types. Application vendors fueled this drug addiction by building increasingly powerful transaction managers and introducing extensions like last participant support. The XA protocol and the strong consistency provided by transactions does not model real life where eventual consistency abounds. 

In a distributed system built on the microservices architectural style deployed on the cloud the implicit guarantees provided by the default rollback of the XA protocol no longer work. In distributed systems the uncertainty of the state has to be explicitly dealt by the application.  This inconsistency in a distributed application is dealt with by a Saga or a Process Manager. Note that saga's and process manager's are NOT antithetical to DDD. 

Data consistency in a microservices system cannot be implemented by distributed transactions. Use the SAGA pattern to string together a series of local transactions with compensation events. Using Saga's or process managers correctly will not violate your context boundaries. In fact using a higher level state machine will allow you to focus more on the domain concerns rather than bike shedding over the implementation(re-sequencing, de-duplication) of an event driven architecture.

In today’s distributed world, consider global transaction managers an architecture smell. See Kevin Hoffman's article on this topic:  Distributed Transactions in a Cloud-Native, Microservice World.

Pat Helland in his updated paper Life Beyond Distributed Transactions states
In a system that cannot count on distributed transactions, the management of uncertainty must be implemented in the business logic. The uncertainty of the outcome is held in the business semantics rather than in the record lock. This is simply workflow. Nothing magic, just that we can’t use distributed transaction so we need to use workflow.
Another excellent source of insight on this topic is from Josh Long and Kenny Bastani in their excellent book Cloud Native Java. From See JTA and XA Transaction Management in Appendix A Using Spring Boot with Java EE in CloudNativeJava book.

Distributed transactions gate the ability of one service to process transactions at an independent cadence. Distributed transactions imply that state is being maintained across multiple services when they should ideally be in a single microservice. Ideally, services should share state not at the database level but at the API level, in which case this whole discussion is moot: REST APIs don’t support the X/Open protocol, anyway! There are other patterns for state synchronization that promote horizontal scalability and temporal decoupling, centered around messaging. You’ll find more on messaging in our discussion of messaging and integration.
From https://www.safaribooksonline.com/library/view/Cloud+Native+Java/9781449374631/part03ch02.html#messaging

With event carried state transfer or event sourcing  We can use the saga pattern and design compensating transactions for every service with which we integrate and any possible failure conditions, but we might be able to get away with something simpler if we use a message broker. Message brokers are conceptually very simple: as messages are delivered to the broker, they’re stored and delivered to connected consumers. If there are no connected consumers, the broker will store the messages and redeliver them upon connection of a consumer.
Message brokers have their own, resource-local notion of a transaction. A producer may deliver a message and then, if necessary, withdraw it, effectively rolling the message back. A consumer may accept delivery of a message, attempt to do something with it, and then acknowledge the delivery—or, if something should go wrong, return the message to the broker, effectively rolling back the delivery. Eventually both sides will agree upon the state. This is different than a distributed transaction in that the message broker introduces the variable of time, or temporal decoupling. In doing so, it simplifies the integration between services. This property makes it easier to reason about state in a distributed system. You can ensure that two otherwise non-transactional resources will eventually agree upon state. In this way, a message broker bridges the two otherwise non transactional resources.
If you wan to do Distributed Transactions In Spring, With And Without XA take a look at this article from David Syer and the code samples that go along with it on how to do non XA distrubuted transactions with Spring 

Best Efforts 1PC Pattern
The Best Efforts 1PC pattern is fairly general but can fail in some circumstances that the developer must be aware of. This is a non-XA pattern that involves a synchronized single-phase commit of a number of resources. Because the 2PC is not used, it can never be as safe as an XA transaction, but is often good enough if the participants are aware of the compromises. Many high-volume, high-throughput transaction-processing systems are set up this way to improve performance.

So in summary
  • Prefer Resource Local best effort single single resource Transactions over global transactions
  • Prefer Spring’s @Transactional variant over EJB’s @javax.ejb.TransactionAttribute or JTA’s @javax.transaction.Transactional
Moving away from distributed transactions requires an adjustment in mindset to make use of new paradigms. Move away from JTA to an architecture and implementation style where you model the domain uncertainty and make the best effort to model and handle it in the business logic instead of delegating this core responsibility to the underlying platform. 


Resources:
  1. Daniel Frey has created A Demo App to illustrate the use of the JPATransactionManager to handle Database and JMS “rollbacks”. distributed-tx 


Tuesday, September 5, 2017

Porting WebSphere Datapower to Pivotal Cloud Foundry


Locked in and married unto death with WebSphere Datapower ? There is a way out where you can emerge stronger. Read on ...

Authors

- [Rohit Kelapure](https://www.linkedin.com/in/rohitkelapure/)
- [Elena Neroslavskaya](https://www.linkedin.com/in/neros/)

Replatforming 

Run DP in PCF with the native Docker support.
_Docker image of DP_
https://hub.docker.com/r/ibmcom/datapower/
https://developer.ibm.com/datapower/2016/11/09/using-datapower-for-docker-in-ibm-container-service/

OR

Modernization 

  • Scenario 1: XML Processing with XSLTs at wire speed. Incrementally migrate XSLT flows from DataPower to Spring Boot microservices leveraging java streaming XSLT 2.0/3.0 processors like [SAXON](http://www.saxonica.com/welcome/welcome.xml) and [Altova]. The Spring 5 and Spring boot 2 reactive support will allow us to process all logic reactively in a non-blocking fashion from end-user to server. If the XSLT transformations involve business logic then migrate those business rules to a Rules engine like DROOLs or orchestrate the data rules microservices logic with SpringCloudDataFlow.
  • Scenario 2: Authentication and Authorization, SSL Offload, Security vectors - HTTP threat protection: This is modernized and replaced via a combination of federated authn/authz + Web firewall and networking edge devices with NSX-T or NSX-V.
  • Scenario 3: mini-ESB Protocol Transformation and Governance: Use Spring Integration or Camel light weight implementation of EAI patterns to transform data.
  • Scenario 4: Caching: Leverage Redis or Pivotal Gemfire or Pivotal Cloud Cache to cache data alongside the app and not in the DMZ.
  • Scenario 5: Data Integration- Connectors to Mainframes and other EAI systems: Leverage zOS Connect 2.0 web service support on the mainframe to expose REST APIs for your zOS backend sub-systems like IMS, CICS, DB2, ... or use Java connectors to IMS and CICS. Implement data microservices that consume these APIs and/or use the connectors.
  • Scenario 6: API Gateway: Replace with a custom route service with a software layer 7 service aware router and load balancer like Netflix Zuul or leverage an integrated solution like [Apigee](https://apigee.com/about/blog/developer/edge-microgateway-pivotal-cloud-foundry-technical-updates) or [Istio](https://content.pivotal.io/blog/pivotal-and-istio-advancing-the-ecosystem-for-microservices-in-the-enterprise)

Recommendation:

We recommend following the path of modernization instead of replatforming since dockerizing DP will not yield the full benefits of a cloud native architecture. Modernizing instead of replatforming over the long term will end the dependence on DP and  and replace with more scalable and widely available software and people and process. 

WHY

  1. Running Docker images will give you IaaS efficiencies dropping OPEX cost
  2. Separation of responsibilities. Smaller teams can implement and own individual service capabilities without having a central god governance and transformation point. Choreography instead of orchestration. Smart endpoints, dumb pipes.
  3. Developer productivity with Java non XML code is high.
  4. Setting up a CI pipeline and integrating other DEVOPS tools is easier with microservices.
  5. Debugging is easier in java code than XSLT transforms
  6. Ramp up of developers and provisioning of environments becomes a lot easier.
  7. If Datapower is not being used for data transformation, connectors to backend systems, caching or Authenication and authorization then strangling the XSLT transforms can be done in a phased systematic fashion since the true value  of DP is not being leveraged.


Thursday, August 17, 2017

YES WE CAN - you can push JavaEE apps to CloudFoundry

We all know and love the Java Buildpack - the workhorse for pushing majority of our applications to Cloud Foundry. There is also another gem of a buildpack called the TomEE buildpack. As you can guess from the name it is a close cousin of the Tomcat buildpack with the added enhancement that it supports the JavaEE WebProfile, Full profile* and supports the push of ear files. 

Wait a Minute !!!!!!!!!!!!!!!!!

We can push web profile and full profile applications* packaged as ear and war files to Cloud Foundry and not just plain vanilla spring apps that run on Tomcat ?

Yes siree bob ....

These are the buildpacks we often use in replatforming to move JavaEE apps to Cloud Foundry with minimal changes.


So why go through all this rigmarole and not just push Docker images ? 

Well I contend that pushing ear and war files are better than pushing well formed Docker images because a proper Docker CI image pipeline starts looking like what a buildpack does. So skip all the preamble and discovery and leverage the power of buildpacks. Why transmogrify your app to include OS bits and layers etc ? Deal with the currency you are familiar with i.e. jar, war and ear files. 

All these buildpacks also have magic in the form of  auto-configuration to wire and map your Cloud Foundry bound managed and CUPS services into existing data-sources so that JNDI lookups in your application source don't have to change. This allows for external service configuration to be consumed seamlessly by your data and messaging layers.  

Finally if everything else fails then there is always Docker ... 

You have my attention now ?? Which buildpacks should I use ?

See that depends on three things 1. What is in the apps and 2. Which app server are they coming from

In general if possible we recommend bootifying your application and leveraging the most useful framework components of the JavaEE stack and running your app using the Java Buildpack. If this is not feasible then your first step is to cf push the app using the buildpack of your application server. This will minimize changes needed to your application.

Thereafter I would proceed to nuke ALL the server specific deployment descriptors such that you can run the app  on a generic EE server like TomEE or Payara. If you don't like buildpacks and prefer the fat jar or the uber jar approach instead then bundle the app server within the app and push using the Java Buildpack. 

Well now you have me thoroughly confused ... 

Don't worry here is a picture that will sort you out ...


I end this blog on a cautious note - There are NO silver bullets in software development. 

The benefits from the cloud  are maximized form the agility gained from running lighter weight, smaller scale well bounded cloud native apps. Moving monolithic apps to the platform without modernization will yield a benefit that you should invest back into modernizing your application along the 15 factor continuum.


* Note full profile app support in TomEE is not default. You have to do some acrobatics to bundle the right TomEE distribution into the TomEE offline/online buildpack
* Also note some aspects of JavaEE will NOT work in the cloud for instance if there are any 2pc transactions then those transaction managers will obviously not work in a platform that has ephemeral containers and file system.